This is how we did it in GrowthOS1 and the reasons behind this approach. Keep reading while we unveil our secret sauce around the backbone of our system.
“Let's train the AI on our company.”
We hear some version of this sentence increasingly often.
Upload the brand guidelines. Add the product documentation. Give it the sales presentations, previous campaigns, customer research, SOPs, case studies and everything else the company knows.
Then the AI will understand the business.
Conceptually, that is correct. Technically, however, what happens next is usually very different from what people imagine.
In most implementations, you are not actually training the AI model.
You are building a knowledge system around it.
And that distinction becomes important when you start building AI into real business processes.
Training and giving AI knowledge are not the same thing
When you upload 500 documents to an AI system, the model does not normally absorb those documents into its neural network.
Its weights do not change.
Instead, a retrieval system creates an index of your information. When somebody asks a question or an AI agent needs to perform a task, the system searches that index, identifies the pieces of information that appear relevant, and gives those pieces to the model as additional context.
This architecture is generally known as Retrieval-Augmented Generation, or RAG.
Think about it less like training a new employee and more like giving an extremely capable employee access to a very well-organized company library.
Theo Moulos - CSO GrowthhackersThe intelligence comes from the model. The company-specific knowledge comes from the library. The retrieval system connects the two.
This distinction becomes particularly important when AI is embedded into an operating system like GrowthOS, rather than used as a standalone chatbot. The objective is to have AI participate in actual marketing work.
A content agent needs to understand the brand before creating an article. A synthetic persona needs access to customer and product information. An assistant needs to understand previous research. A campaign analysis may need historical context. A growth agent may need to know the company's positioning, competitors, products, experiments and previous decisions.
The underlying problem therefore isn't simply which LLM should we use?
There are really two questions:
Which model should perform the task?
And:
Where should the company's knowledge live, and how should the model retrieve it?
Those two decisions do not necessarily need to have the same answer.
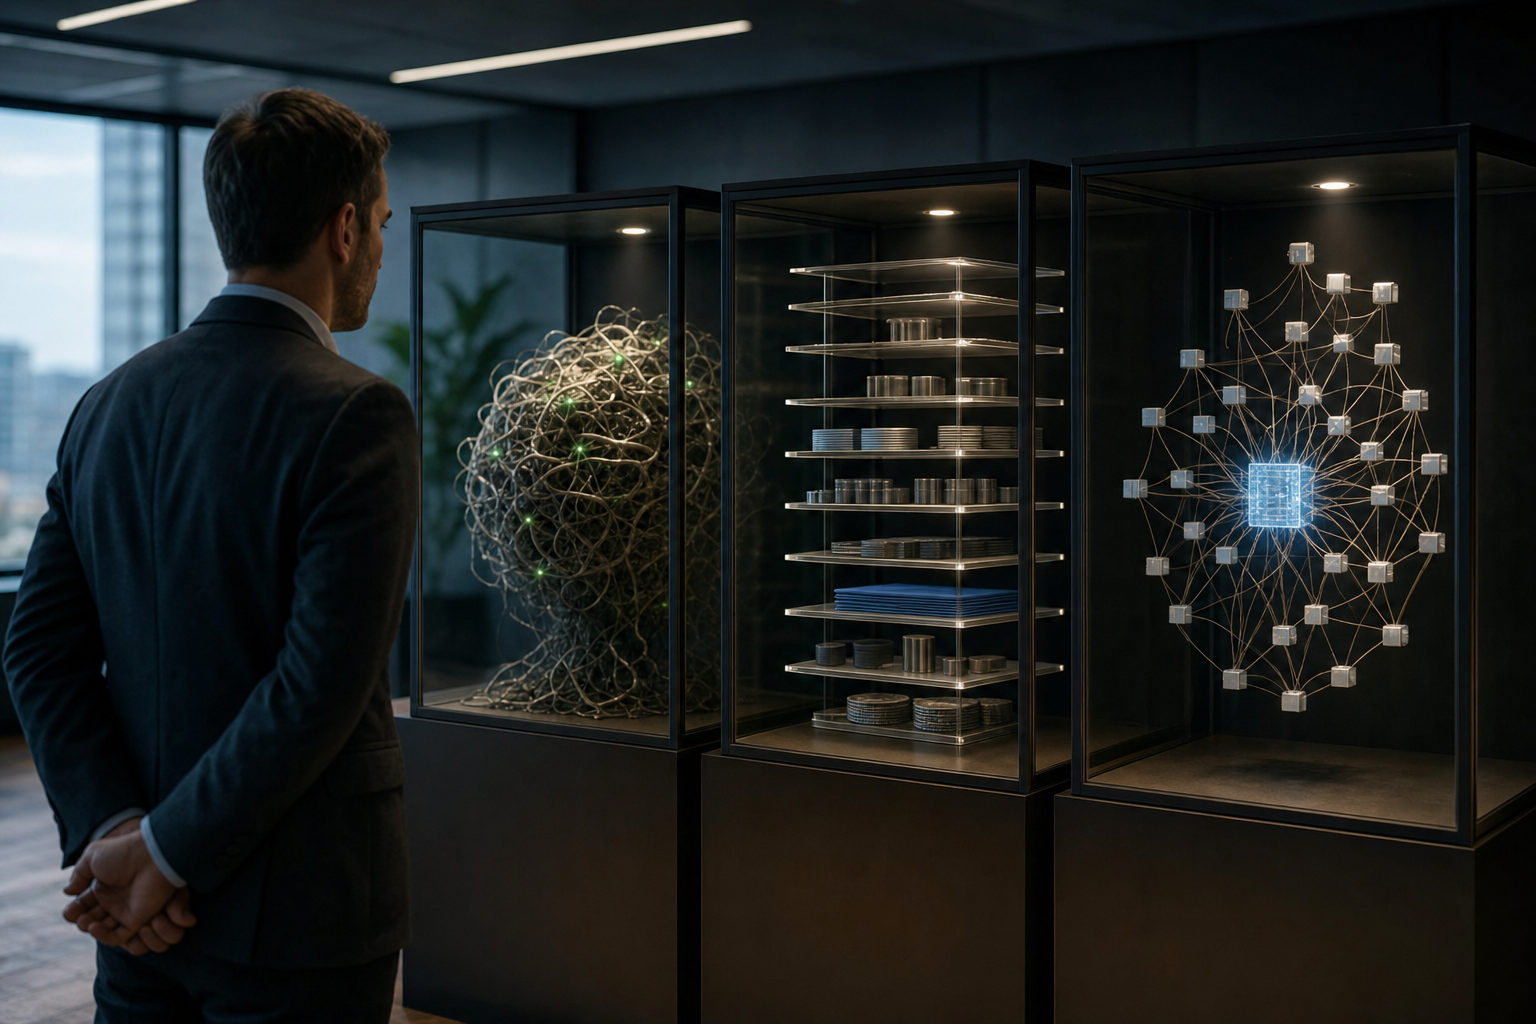
The three vendor approaches
All three can use your documents. Only OpenAI and Gemini give you a managed search store you can point the product at.
OpenAI vector store | Gemini File Search | Claude | |
What it is | Managed chunk + embed + search | Managed chunk + embed + search | No first-party search store |
In Growth OS | Vector Store Management | Gemini File Search | Writer only (you must retrieve elsewhere) |
Default for this product | Yes | Opt-in | Not a store option |
Trains the model? | No | No | No |
OpenAI: the conventional vector-store approach
OpenAI provides managed vector stores.
You upload documents and OpenAI automatically parses, chunks, embeds and indexes them. When File Search is invoked, the system searches the vector store for information relevant to the current request and provides those results to the model.
This is the architecture we initially adopted in GrowthOS.
And there is a good reason for it.
You don't have to build your own vector database, embedding pipeline, chunking infrastructure and retrieval layer just to give an application access to company documents.
More importantly, retrieval can be controlled.
Documents can carry attributes that can be used as filters. Search can return a configurable number of results, use ranking options and score thresholds, and even rewrite a natural-language query before performing the vector search.
That matters when the knowledge base becomes large.
Imagine that GrowthOS contains information about products, brand strategy, personas, competitors, campaigns, events, courses and previous growth experiments.
You don't necessarily want every AI operation searching everything.
A content agent working on Product A may need Product A documentation, the global brand guidelines and the relevant persona research. It probably doesn't need the documentation for an unrelated course.
This is where RAG becomes more than simply “uploading files.”
The quality of an AI knowledge system depends heavily on what you retrieve, when you retrieve it and what you send to the model.
The OpenAI cost model
There is another dimension that becomes important once these systems move from demos to production: cost.
At the time of writing, OpenAI provides the first 1 GB of vector-store storage free and charges $0.10 per GB per day beyond that. File Search tool calls through the Responses API are priced at $2.50 per 1,000 calls. Retrieved content is then processed as model input.
For a normal company's curated knowledge base, this can be extremely inexpensive.
If your store remains below 1 GB, your storage cost can effectively be zero.
If you make 1,000 AI generations in a month and every generation performs one File Search call, the search component is roughly $2.50, before the model-token costs.
Nothing particularly frightening there.
But the economics start changing when companies stop uploading a curated knowledge base and start saying:
“Why don't we just connect the entire Drive?”
Now you may be dealing with years of presentations, PDFs, reports, research, exports and duplicated documents.
And persistent storage starts to matter.
Gemini changes the economics
Google's Gemini File Search follows broadly the same RAG concept.
Documents are imported, chunked and indexed into a File Search store. At generation time, Gemini retrieves relevant information and uses it as context for the response.
But Google's pricing model is interesting.
At the time of writing, File Search storage is free. Query-time embedding generation is also free. Google charges $0.15 per million tokens for the embeddings created when documents are indexed, while retrieved document tokens are billed as normal model input.
In other words, Gemini moves much more of the retrieval cost toward ingestion rather than ongoing storage and search.
That changes the calculation for large corporate knowledge bases.
Suppose you have a relatively small, carefully maintained brand knowledge base.
The difference may be irrelevant.
Now suppose you want to index a substantial archive containing years of research, presentations, product information and marketing documentation and keep querying it thousands of times.
The economics become much more interesting.
OpenAI's model charges for storage beyond the free allowance and File Search calls.
Gemini charges for creating the embeddings when information is indexed, but not for File Search storage or query-time embeddings.
That doesn't automatically make Gemini “better.”
It makes the architecture worth thinking about.
And then there is Claude
Claude is where the comparison becomes particularly interesting because Anthropic approaches documents differently.
Claude's Files API allows developers to upload a file once and reference that file in later Messages API requests rather than repeatedly uploading the raw document.
That is useful.
But storing a file is not the same thing as maintaining a managed searchable vector store.
Claude can work extremely well with long documents and large contexts. Anthropic itself recommends specific prompting techniques for large-document workloads, including placing long documents before the query and structuring multiple documents clearly.
Claude also provides prompt caching.
For information that is reused repeatedly, caching can materially change the economics. Anthropic's documented pricing structure makes a five-minute cache write 1.25 times the normal input price, while cache hits cost 0.1 times the normal input price. Longer one-hour cache writes have a different multiplier.
That can be excellent when you have a stable body of context that is repeatedly reused.
It is not, however, the same architecture as searching a large persistent knowledge base for a handful of relevant passages.
And this leads to a useful realization.
Costs (list prices, September 2026)
Vendor prices change. Recheck OpenAI retrieval and Gemini File Search before budgeting.
Charge | OpenAI vector store | Gemini File Search | Claude |
First index | Included (recovered later) | $0.15 per 1M tokens, once | N/A (no index) |
Storage | First 1 GB free, then $0.10 / GB / day | Free | Files API quota (~1 TB/org); no vector fee |
Each search | $2.50 per 1,000 file-search calls | Free | You pay whatever store you search |
Retrieved text in the prompt | Normal OpenAI input tokens | Normal Gemini input tokens | Full docs, or cache (~1.25× write, ~0.1× read) |
Rough examples
Small brand store under 1 GB, mostly unused: both OpenAI and Gemini are cheap. OpenAI storage is often $0.
1,000 generations/month that each search the store: about $2.50/month in OpenAI search fees, $0 search fees on Gemini (plus whichever model’s input tokens).
A large Drive dump that sits for months: OpenAI can charge every day after 1 GB. Gemini storage stays $0.
Re-uploading changed files: Gemini bills only the new index tokens at $0.15/1M.
Claude is not cheaper for a large knowledge base. Every generation must either see the full documents or use another store.
Your model and your knowledge store don't have to come from the same company
This is probably the most important architectural lesson.
There is no fundamental reason why using Claude for generation means your knowledge needs to be stored by Anthropic.
You could retrieve relevant company knowledge from an OpenAI vector store and send those results to Claude.
You could retrieve from Gemini File Search and use another model to perform a subsequent task, depending on how your application is architected.
Or you could maintain your own retrieval infrastructure and treat models as interchangeable reasoning and generation engines.
Once you separate knowledge retrieval from generation, the architecture becomes much more flexible.
Instead of asking:
Which AI should our company use?
the better question becomes:
Which AI should perform this particular job, and what information should it receive before doing it?
That is a very different way of thinking about enterprise AI.
This is why we call it AI Training in GrowthOS, even though technically it isn't training
Inside GrowthOS we use the term AI Training because it describes the business outcome better than the underlying engineering.
A marketing manager shouldn't need to understand embeddings before uploading the company's positioning document.
From their perspective, they are teaching GrowthOS about their business.
Underneath, however, we deliberately keep knowledge separate from the models themselves.
The company's documents form part of its AI knowledge layer.
That knowledge can then be retrieved when GrowthOS creates content, works with personas, assists users, analyzes information or runs AI-powered workflows.
This separation is important because models are changing extraordinarily quickly.
The model that is best for a particular job today may not be the model we want to use six months from now.
Your company's knowledge shouldn't have to start again every time that happens.
The bigger idea: your company needs an AI-readable DNA
This is where the conversation becomes much bigger than OpenAI versus Gemini versus Claude.
A folder containing 10,000 documents is not automatically organizational knowledge.
It is simply 10,000 documents.
For AI to become genuinely useful inside a company, we need to think about what constitutes the company's DNA.
What are our products?
Who are our customers?
What do we believe?
How do we position ourselves?
Who are our competitors?
What have we tried before?
What worked?
What failed?
What tone do we use?
What claims are we allowed to make?
What processes do we follow?
What research have we conducted?
What have customers told us?
What decisions have already been made?
The challenge is increasingly not access to an intelligent model. Powerful models are becoming available from multiple vendors.
The challenge is giving those models the right organizational context at the right moment.
And that is why AI Training, despite the slightly inaccurate technical name, is becoming such an important part of GrowthOS.
We are not trying to train another foundation model.
We are building the layer between a company's knowledge and the increasingly large ecosystem of AI models and agents that can act on that knowledge.
So which one should you use?
For GrowthOS today, OpenAI remains the production default for the knowledge store because it is already integrated throughout the platform and gives us a mature managed retrieval architecture.
Gemini File Search is particularly interesting for larger knowledge bases and high retrieval volumes because of its current storage and retrieval economics.
Claude remains extremely interesting as a model for reasoning and writing, but we should think of that separately from the question of where a large searchable company knowledge base lives.
And that is perhaps the biggest takeaway from our experimentation with all three.
Stop thinking about “the AI” as one system.
There is the model.
There is the knowledge.
There is retrieval.
There is context.
There are tools.
There are agents.
And there is the orchestration layer deciding how all of those pieces work together.
That orchestration layer is ultimately where a company's AI advantage will be built.
Because everyone can access powerful models.
The harder part is making those models understand your company.
Frequently Asked Questions
Am I truly 'training' an AI when I upload my company's documents to it?
In most implementations, you are not actually training the AI model by uploading documents. Instead, you are building a knowledge system around it. The AI model's neural network weights do not change. A retrieval system indexes your information, and when a query comes, it finds relevant pieces and provides them to the AI as context. This process is known as Retrieval-Augmented Generation (RAG), which is more like giving an intelligent employee access to a well-organized library rather than training them directly.
What is Retrieval-Augmented Generation (RAG) and how does it work?
Retrieval-Augmented Generation (RAG) is an architecture where a retrieval system creates an index of your information. When a question is asked or a task needs to be performed, the system searches this index, identifies relevant pieces of information, and gives them to the AI model as additional context. The intelligence comes from the model, while the company-specific knowledge comes from this 'library' of documents, with the retrieval system connecting the two. This allows the AI to use your specific data without retraining its core model.
How do OpenAI, Gemini, and Claude differ in their approach to managing company knowledge for AI?
OpenAI and Gemini both offer managed search stores where documents are parsed, chunked, embedded, and indexed. OpenAI uses vector stores with configurable retrieval, while Gemini uses File Search, differing notably in their cost models for storage and ingestion. Claude, however, does not provide a first-party search store. Instead, its Files API allows developers to upload and reference documents in later requests, focusing on long document processing and offering prompt caching for efficiency. Developers need to manage retrieval externally when using Claude for custom knowledge bases.
Why is it important to control retrieval when building an AI knowledge system?
Controlling retrieval is crucial, especially as a knowledge base grows large. For example, if GrowthOS contains information on products, brand strategy, and campaigns, you don't want every AI operation searching everything. A content agent working on Product A needs Product A documentation, global brand guidelines, and relevant persona research, but probably not documentation for an unrelated course. The quality of an AI knowledge system heavily depends on *what* is retrieved, *when* it's retrieved, and *what* is sent to the model, ensuring relevance and efficiency.
What is the key distinction between 'training AI' and 'giving AI knowledge' as described in the article?
The article explains that when you upload documents to an AI system, you are typically not 'training' the AI model by altering its neural network weights. Instead, you are building a knowledge system around it, often using Retrieval-Augmented Generation (RAG). This means an index of your information is created, and relevant pieces are retrieved and provided to the AI model as context when needed. The AI's core intelligence remains, but it gains company-specific knowledge from this 'library' rather than being fundamentally retrained.
Notes
- ↩
A quick note on what GrowthOS is:
Throughout this article, we refer to GrowthOS, so it is worth explaining what it actually is.
GrowthOS is an AI-powered marketing operating system developed by GrowthHackers. It brings the different disciplines of modern marketing into one environment, combining digital marketing, growth hacking, content, SEO and AI Search Optimization (SAIO/GEO), social media, performance marketing, experimentation, analytics and execution.
But GrowthOS is not simply another collection of marketing tools.
At its core, it connects strategy, knowledge and execution. Teams can move from research and planning to campaigns, experiments and tasks inside the same system, while AI works across those activities instead of living in a separate chat window.
This is why GrowthOS includes capabilities such as AI-powered content creation, Synthetic Personas and virtual focus groups, growth experimentation, marketing analytics, advanced task and sprint management, and AI agents for repetitive or scalable workflows.
An important part of that architecture is what we call the company's AI DNA: the accumulated knowledge that AI needs in order to understand the organization it is working for. This can include positioning, products, services, personas, customer research, competitors, brand guidelines, previous campaigns, experiments, processes, documents and other company-specific knowledge.
Instead of treating AI as a generic assistant that starts from zero with every prompt, GrowthOS is designed to give AI access to this organizational context when it performs a task.
And that is precisely why the question of where this knowledge lives and how AI retrieves it matters so much.